Web scraping services that deliver clean, ready-to-use data
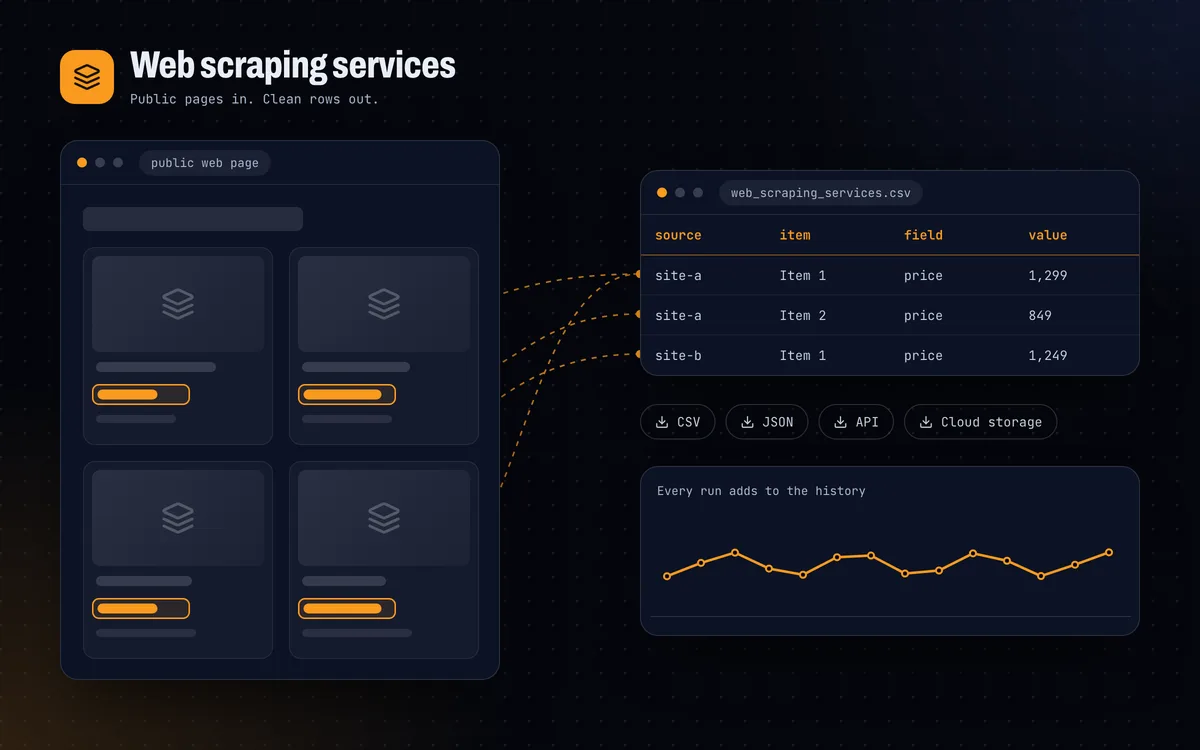
Tell us which websites and fields you need. We build the scrapers, run them on your schedule, check the output and fix them when a site changes. You receive files or an API, not code to maintain.
Pricing, assortment and planning meetings work from what the market shows today, not a spreadsheet someone filled in last quarter.
Hours back for your team
Analysts stop copying pages into spreadsheets and spend the time on the questions the data answers.
One format across every source
Ten websites with ten layouts arrive as one table with one set of column names, so joins and dashboards just work.
Where it is used
Common ways teams put this data to work. Yours may be different; tell us in the form below.
01
Competitive price tracking
Know when competitors change price, stock or promotions, without checking pages by hand.
02
Market and demand research
Collect listings, reviews or job postings across many sites into one consistent dataset.
03
Catalogue enrichment
Fill gaps in your own product or company records with public attributes.
04
Datasets for analytics and AI teams
Structured, deduplicated data with a documented schema, ready for a warehouse or model.
More about web scraping services
What "done for you" covers
A scraper is a small program, but a data feed is a service. It needs a schedule, somewhere to run, a way to notice when a site changes, retries when a page fails, checks that the numbers make sense, and a delivery step that lands the file where your team expects it.
We handle all of that. You describe the output you want: the sites, the fields, how often, and where it should arrive. We agree a schema with you, deliver a sample, and then run the feed in production.
Which websites we can collect from
Most public websites can be collected: online stores, marketplaces, listing portals, directories, career pages, travel sites, government notice boards and news sites. Pages that load content with JavaScript are fine; we use a browser only where a page needs one, because plain requests are faster and cheaper to run.
We do not collect data behind a login, and we avoid personal data by default. If a site restricts automated access in its terms, we tell you before we build so you can decide.
What you receive
Each delivery is a clean file or API response with the columns we agreed, a source URL and a collection timestamp on every row. Recurring feeds keep the same schema from run to run, so anything you build on top keeps working.
How it works
You see real data from your own sources before you commit to anything recurring.
01
Scope
You send the sites, fields, volume and schedule. We confirm what is practical and how it should be delivered.
02
Sample
We deliver a small sample or a paid pilot so you can check coverage and quality.
03
Production
We run the feed on schedule, monitor every source and fix scrapers when sites change.
Questions buyers ask
Not covered here? Ask in the quote form and we will answer with your scope.
What formats do you deliver?
CSV, JSON and Excel files, or an API and cloud storage drop for recurring feeds. We agree the schema with you before we start.
What happens when a website changes?
Recurring feeds include monitoring. When a source changes its layout, we update the scraper as part of the plan, and we flag gaps in the data rather than hiding them.
Is web scraping legal?
Collecting publicly visible, non-personal data is common and generally lawful, but it depends on the site, the data and the country. We review the target and the data type with you first and do not bypass logins or collect personal data without a lawful basis. This is not legal advice.
How long does a first delivery take?
Simple single-site projects often deliver a sample within a few working days. Larger or harder sources take longer, and we give an estimate with the quote.
Related services
Most projects combine more than one kind of data. See all services.