Files and API together
Many teams want both: an API for applications and a daily file drop for analysts. Both come from the same pipeline and the same schema, so numbers always match.
Custom web data API
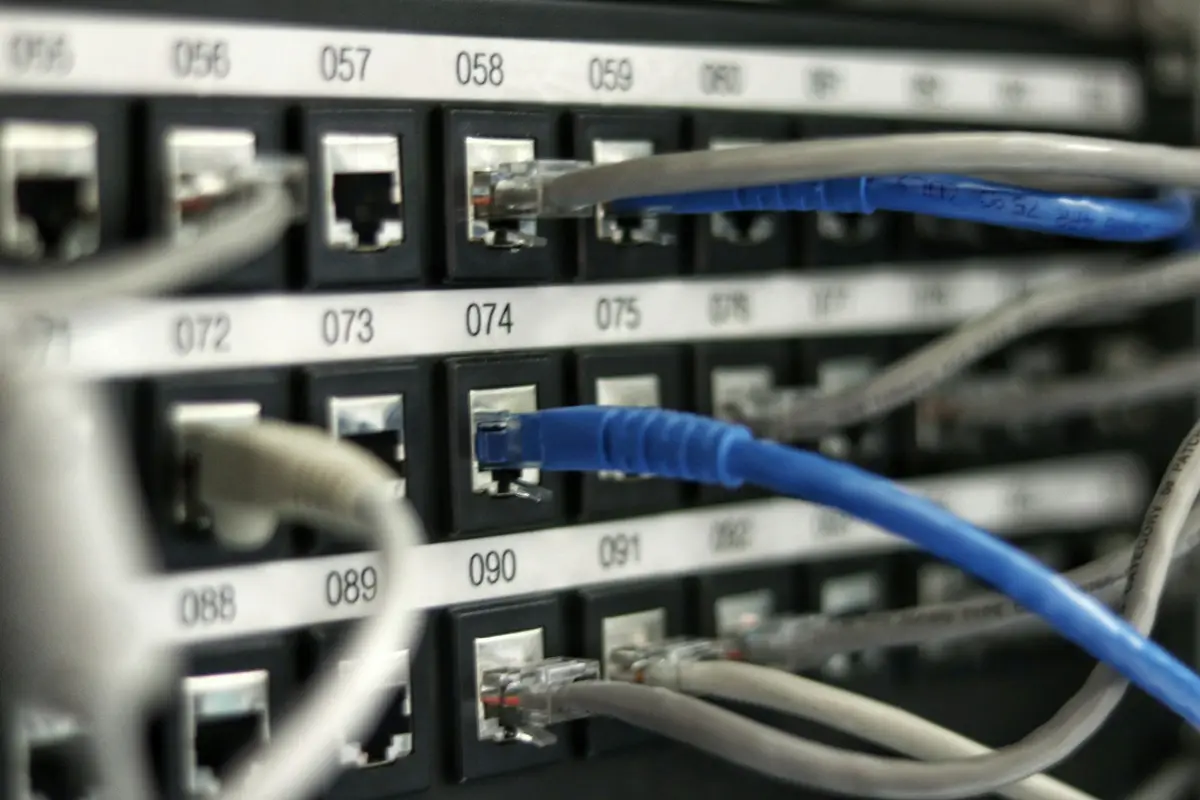
A custom web scraping API gives your applications the data directly. We collect from the sites you need, store the clean results and expose them through documented endpoints with filters and incremental queries, so your systems fetch what changed since the last call.
Prefer email? Write to sales@crawlmine.com. We reply within one working day.
| method | endpoint | returns |
|---|---|---|
| GET | /v1/feeds/prices?since=2026-01-10 | changed rows |
| GET | /v1/feeds/prices/runs/latest | run status |
| GET | /v1/feeds/prices/schema | field list |
Pick the fields you need. We agree the exact schema with you before the first run, and every row carries its source and collection time.
Columns are named consistently and values are cleaned, so the file opens straight into a spreadsheet, BI tool or warehouse.
| method | endpoint | returns |
|---|---|---|
| GET | /v1/feeds/prices?since=2026-01-10 | changed rows |
| GET | /v1/feeds/prices/runs/latest | run status |
| GET | /v1/feeds/prices/schema | field list |
Illustrative layout only. Real samples use your sites and fields.
Your engineers integrate one documented API instead of maintaining collection jobs.
Incremental queries keep loads small and fast.
Run metadata tells your systems when fresh data is ready and how complete it is.
Common ways teams put this data to work. Yours may be different; tell us in the form below.
Let your repricing service pull fresh competitor prices directly.
Show market data inside your own app without running scrapers.
Connect BI tools to a live, documented source.
Pull incremental changes on a schedule into your warehouse.
Many teams want both: an API for applications and a daily file drop for analysts. Both come from the same pipeline and the same schema, so numbers always match.
You see real data from your own sources before you commit to anything recurring.
You send the sites, fields, volume and schedule. We confirm what is practical and how it should be delivered.
We deliver a small sample or a paid pilot so you can check coverage and quality.
We run the feed on schedule, monitor every source and fix scrapers when sites change.
Not covered here? Ask in the quote form and we will answer with your scope.
No. It is your own feed: we run the collection for your agreed sources and fields, and the API serves the clean results.
Limits and availability targets are agreed in writing for each project, based on how your systems use the API.
Yes. We can call your endpoint when a run completes, with a summary of what changed.
Most projects combine more than one kind of data. See all services.
Talk to us directly
sales@crawlmine.comSend the websites and fields you need. A person on our team reads every message.
Tell us which websites and fields you need. We confirm what is practical, how it should be delivered and what it costs.
Request received.
Thanks. It is with our team at sales@crawlmine.com, and we reply within one working day.