Industry · AI and machine learning
Web data for AI and machine learning teams
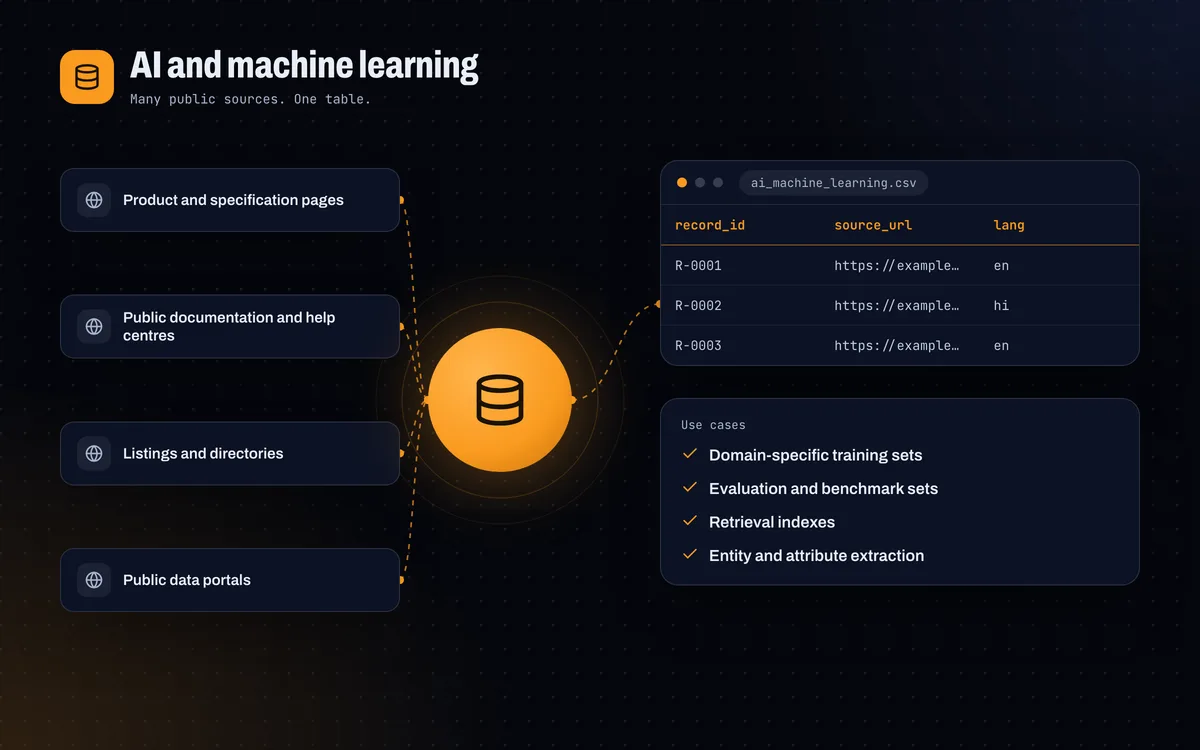
AI and machine learning teams need web data that is structured, deduplicated and traceable. We collect public web data into documented datasets with a source URL and timestamp on every row, for training, evaluation, retrieval and analytics, and we exclude personal data by default.
Prefer email? Write to sales@crawlmine.com. We reply within one working day.
Why tracking this market by hand fails
Raw crawls are full of duplicates, boilerplate, broken encodings and mixed languages. Without provenance, nobody can say where a record came from or whether it may be used. Cleaning takes more time than modelling.
Public sources we collect from
- Product and specification pages
- Public documentation and help centres
- Listings and directories
- Public data portals
We collect publicly visible, non-personal data and do not bypass logins.
AI and machine learning use cases for web data
How ai and machine learning teams use scraped public data, and the fields that feed each use case.
- 01
Domain-specific training sets
Collect structured records from the sites that define your domain.
- record
- category
- source url
- 02
Evaluation and benchmark sets
Build categorised, labelled samples to test model quality.
- input
- label
- source
- 03
Retrieval indexes
Keep an index of public product, policy or specification pages fresh.
- url
- title
- updated at
- 04
Entity and attribute extraction
Turn pages into entities with typed attributes for knowledge graphs.
- entity
- attribute
- value
How web data helps the business
The value is not the rows. It is the decisions your team can make with current, complete numbers.
More time on models
Engineers start from clean, documented data.
Traceable inputs
Every record links back to its source and collection time.
Repeatable refreshes
New dataset versions come from the same pipeline and schema.
A sample of the output
Every delivery uses one schema across all sources, with a source URL and collection timestamp on each row.
| record_id | source_url | lang | category | tokens |
|---|---|---|---|---|
| R-0001 | https://example.com/a | en | specs | 412 |
| R-0002 | https://example.com/b | hi | reviews | 188 |
| R-0003 | https://example.com/c | en | policy | 1,034 |
Illustrative layout only. Real samples use your sites and fields.
Services for ai and machine learning
Start with one, combine several. Each is built, run and maintained by us.
-
-
-
-
How it works
You see real data from your own sources before you commit to anything recurring.
- 01
Scope
You send the sites, fields, volume and schedule. We confirm what is practical and how it should be delivered.
- 02
Sample
We deliver a small sample or a paid pilot so you can check coverage and quality.
- 03
Production
We run the feed on schedule, monitor every source and fix scrapers when sites change.
Questions buyers ask
Not covered here? Ask in the quote form and we will answer with your scope.
Do you provide copyrighted text in bulk?
We focus on facts and attributes. We discuss rights and permitted use of any text content with you before collecting it. This is not legal advice.
Which formats do you deliver?
Parquet, JSON Lines, CSV or direct database loads, with a data dictionary.
Do you remove personal data?
We exclude personal data by default and agree the rules with you for each source.
Other industries
See all industries or browse every use case.
Talk to us directly
sales@crawlmine.comTell us about your ai and machine learning data needs. A person on our team reads every message.
Send us the sites tonight. Data by morning.
Tell us which websites and fields you need. We confirm what is practical, how it should be delivered and what it costs.
- Goes straight to sales@crawlmine.com
- Reply within one working day
- A sample or pilot before any recurring plan
- NDA available before you share details
Request received.
Thanks. It is with our team at sales@crawlmine.com, and we reply within one working day.